Connect OpenClaw to the gateway
Start a DeepSeek Flash session, read a project file, then switch to another gateway model. Follow the numbered steps below with your delivered Multi-Model Gateway key and address.
Configure once · switch models inside the Agent
Includes the eight-model configuration and setup instructions. Merge into your existing settings and replace the key or path placeholders locally.
Individual files remain available in the numbered steps below.
Before you begin
- Have your activated gateway key and its confirmed endpoint ready.
- Choose a local project with a README.md for the first conversation.
- Run shell commands in Terminal on macOS / Linux, or inside WSL on Windows. Paste prompts and slash commands inside the Agent.
Use the gateway credentials and model IDs in this guide. A direct DeepSeek Platform key, endpoint or setup script configures a different service.
1. Install and check your version
Install the Agent using its official guide below. Terminal examples use macOS / Linux or Windows WSL. If already installed, check your version and continue.
For a new installation, finish OpenClaw onboarding and install its local Gateway service first. This service is separate from our model API.
Run in Terminal ·Terminal
npm install -g openclaw@latest
openclaw onboard --install-daemon2. Save your key
Add this line to ~/.openclaw/.env. Create the directory and file if needed. Use the same user home or profile that runs your OpenClaw Gateway.
Replace the placeholder on your computer and keep the file private. Restart the Agent after saving.
Configuration ·~/.openclaw/.env
MULTI_MODEL_API_KEY=REPLACE_WITH_YOUR_DELIVERED_GATEWAY_KEY3. Configure the gateway and models
If the file already exists, merge these fields and keep your other settings. Add to existing JSON objects or YAML sections; do not paste a second top-level object.
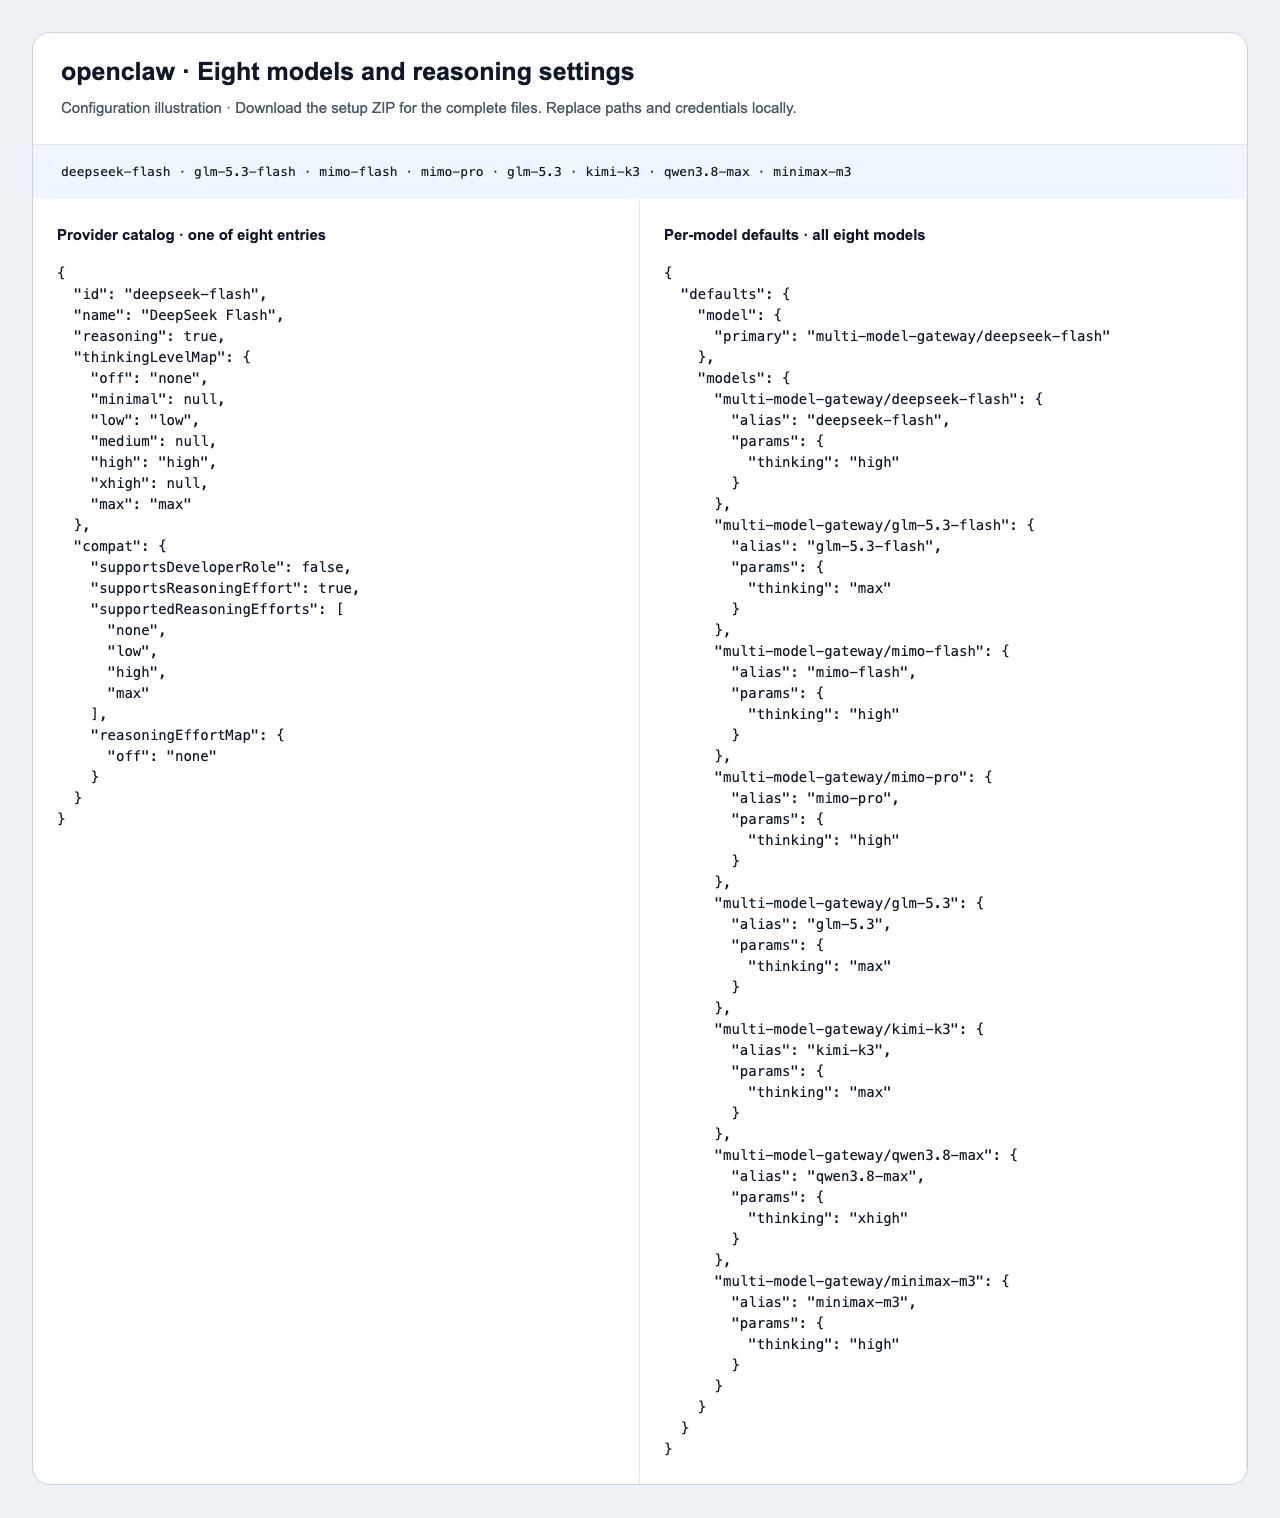
This configuration includes the complete model list. DeepSeek Flash is the starting model; choose a different one inside the Agent later.
Merge every gateway entry into an existing agents.defaults.models map. If your version uses modelPolicy.allow, add multi-model-gateway/* to its existing list; preserve the other allowed entries and any agent-specific restrictions.
Configuration ·~/.openclaw/openclaw.json · merge with existing settings
Merge into ~/.openclaw/openclaw.json, preserving existing providers, agents and allowlists. Keep your key in .env and restart the local OpenClaw Gateway.
{
  "models": {
    "mode": "merge",
    "providers": {
      "multi-model-gateway": {
        "baseUrl": "https://multi-api.deepseekv4pro.com/v1",
        "apiKey": "${MULTI_MODEL_API_KEY}",
        "api": "openai-completions",
        "models": [
          {
            "id": "deepseek-flash",
            "name": "DeepSeek Flash",
            "reasoning": true,
            "thinkingLevelMap": {
              "off": "none",
              "minimal": null,
              "low": "low",
              "medium": null,
              "high": "high",
              "xhigh": null,
              "max": "max"
            },
            "compat": {
              "supportsDeveloperRole": false,
              "supportsReasoningEffort": true,
              "supportedReasoningEfforts": [
                "none",
                "low",
                "high",
                "max"
              ],
              "reasoningEffortMap": {
                "off": "none"
              }
            }
          },
          {
            "id": "glm-5.3-flash",
            "name": "GLM-5.3-Flash",
            "reasoning": true,
            "thinkingLevelMap": {
              "off": null,
              "minimal": null,
              "low": "low",
              "medium": null,
              "high": "high",
              "xhigh": null,
              "max": "max"
            },
            "compat": {
              "supportsDeveloperRole": false,
              "supportsReasoningEffort": true,
              "supportedReasoningEfforts": [
                "low",
                "high",
                "max"
              ]
            }
          },
          {
            "id": "mimo-flash",
            "name": "MiMo V2.6 Flash",
            "reasoning": true,
            "thinkingLevelMap": {
              "off": "none",
              "minimal": null,
              "low": null,
              "medium": null,
              "high": "high",
              "xhigh": null,
              "max": null
            },
            "compat": {
              "supportsDeveloperRole": false,
              "supportsReasoningEffort": true,
              "supportedReasoningEfforts": [
                "none",
                "high"
              ],
              "reasoningEffortMap": {
                "off": "none"
              }
            }
          },
          {
            "id": "mimo-pro",
            "name": "MiMo V2.6 Pro",
            "reasoning": true,
            "thinkingLevelMap": {
              "off": "none",
              "minimal": null,
              "low": null,
              "medium": null,
              "high": "high",
              "xhigh": null,
              "max": null
            },
            "compat": {
              "supportsDeveloperRole": false,
              "supportsReasoningEffort": true,
              "supportedReasoningEfforts": [
                "none",
                "high"
              ],
              "reasoningEffortMap": {
                "off": "none"
              }
            }
          },
          {
            "id": "glm-5.3",
            "name": "GLM-5.3",
            "reasoning": true,
            "thinkingLevelMap": {
              "off": null,
              "minimal": null,
              "low": "low",
              "medium": null,
              "high": "high",
              "xhigh": null,
              "max": "max"
            },
            "compat": {
              "supportsDeveloperRole": false,
              "supportsReasoningEffort": true,
              "supportedReasoningEfforts": [
                "low",
                "high",
                "max"
              ]
            }
          },
          {
            "id": "kimi-k3",
            "name": "Kimi-K3",
            "reasoning": true,
            "thinkingLevelMap": {
              "off": null,
              "minimal": null,
              "low": "low",
              "medium": null,
              "high": "high",
              "xhigh": null,
              "max": "max"
            },
            "compat": {
              "supportsDeveloperRole": false,
              "supportsReasoningEffort": true,
              "supportedReasoningEfforts": [
                "low",
                "high",
                "max"
              ]
            }
          },
          {
            "id": "qwen3.8-max",
            "name": "Qwen3.8 Max",
            "reasoning": true,
            "thinkingLevelMap": {
              "off": "none",
              "minimal": null,
              "low": "low",
              "medium": "medium",
              "high": null,
              "xhigh": "xhigh",
              "max": null
            },
            "compat": {
              "supportsDeveloperRole": false,
              "supportsReasoningEffort": true,
              "supportedReasoningEfforts": [
                "none",
                "low",
                "medium",
                "xhigh"
              ],
              "reasoningEffortMap": {
                "off": "none"
              }
            }
          },
          {
            "id": "minimax-m3",
            "name": "MiniMax M3",
            "reasoning": true,
            "thinkingLevelMap": {
              "off": "none",
              "minimal": null,
              "low": null,
              "medium": null,
              "high": "high",
              "xhigh": null,
              "max": null
            },
            "compat": {
              "supportsDeveloperRole": false,
              "supportsReasoningEffort": true,
              "supportedReasoningEfforts": [
                "none",
                "high"
              ],
              "reasoningEffortMap": {
                "off": "none"
              }
            }
          }
        ]
      }
    }
  },
  "agents": {
    "defaults": {
      "model": {
        "primary": "multi-model-gateway/deepseek-flash"
      },
      "models": {
        "multi-model-gateway/deepseek-flash": {
          "alias": "deepseek-flash",
          "params": {
            "thinking": "high"
          }
        },
        "multi-model-gateway/glm-5.3-flash": {
          "alias": "glm-5.3-flash",
          "params": {
            "thinking": "max"
          }
        },
        "multi-model-gateway/mimo-flash": {
          "alias": "mimo-flash",
          "params": {
            "thinking": "high"
          }
        },
        "multi-model-gateway/mimo-pro": {
          "alias": "mimo-pro",
          "params": {
            "thinking": "high"
          }
        },
        "multi-model-gateway/glm-5.3": {
          "alias": "glm-5.3",
          "params": {
            "thinking": "max"
          }
        },
        "multi-model-gateway/kimi-k3": {
          "alias": "kimi-k3",
          "params": {
            "thinking": "max"
          }
        },
        "multi-model-gateway/qwen3.8-max": {
          "alias": "qwen3.8-max",
          "params": {
            "thinking": "xhigh"
          }
        },
        "multi-model-gateway/minimax-m3": {
          "alias": "minimax-m3",
          "params": {
            "thinking": "high"
          }
        }
      }
    }
  }
}
4. Restart the Gateway
Restart your local OpenClaw Gateway to load its configuration and .env. Then open the TUI or dashboard with the command below.
The dashboard connects to your local OpenClaw service. Its pairing token is different from the Multi-Model API key stored in .env.
Run in Terminal ·Terminal
openclaw gateway restart
openclaw tui5. Choose reasoning effort
Start on DeepSeek Flash. Choose Low, send a short file-reading task, then choose High and repeat. Check the current setting after each change. A longer answer by itself does not prove the effort changed.
Effort means how much reasoning to request. Kimi K3, GLM 5.3 and GLM 5.3 Flash offer Low / High / Max with thinking always enabled. Choose Low for shorter reasoning; there is no Off option. Their model default is Max, but a client setting can override it. DeepSeek and Qwen have their own intensity levels listed below.
MiMo has an On / Off switch; High is the client's label for On. MiniMax M3 supports Off / Auto / On through thinking.type (disabled / adaptive / enabled). Its effort-only menus expose Off and High (On); Auto needs a native thinking control. These modes are not separate Low / High / Max intensities. Follow this Agent's default and switching instructions below; a supported control does not set a session's starting value.
The supplied agents.defaults.models entries set params.thinking separately for each model: High for DeepSeek, Max for Kimi and GLM, XHigh for Qwen, and High (On) for MiMo and MiniMax. These defaults are separate from thinkingLevelMap, where null disables an unsupported choice.
Send /think low or /think high as a message by itself to change the saved session setting. /think reports the current level; /status shows the requested and effective settings. Send /think default to clear the session override and inherit the configured default. It does not ask the upstream model to choose a default. Per-agent defaults can still override the shared model settings.
The TUI uses the same local OpenClaw Gateway configuration as the browser Control UI. Recheck /think after changing models or resuming a saved session.
- DeepSeek Flash
- Off / Low / High / Max
- Starting setting: high
- Start with Low; choose High or Max for more reasoning, or Off to disable thinking. Medium and XHigh requests map to High; Ultra maps to Max.
- GLM-5.3-Flash
- Low / High / Max
- Starting setting: max
- Choose Low for shorter reasoning, High for more reasoning, or Max for the largest budget. Thinking is always enabled; there is no Off option. The model default is Max unless the client sends a different effort.
- MiMo V2.6 Flash
- Off / On
- Starting setting: On (High)
- Choose On to enable thinking or Off to disable it. In clients that label On as High, choose High. There are no separate Low, Medium or High intensities.
- MiMo V2.6 Pro
- Off / On
- Starting setting: On (High)
- Choose On to enable thinking or Off to disable it. In clients that label On as High, choose High. There are no separate Low, Medium or High intensities.
- GLM-5.3
- Low / High / Max
- Starting setting: max
- Choose Low for shorter reasoning, High for more reasoning, or Max for the largest budget. Thinking is always enabled; there is no Off option. The model default is Max unless the client sends a different effort.
- Kimi-K3
- Low / High / Max
- Starting setting: max
- Choose Low for shorter reasoning, High for more reasoning, or Max for the largest budget. Thinking is always enabled; there is no Off option. The model default is Max unless the client sends a different effort.
- Qwen3.8 Max
- Off / Low / Medium / XHigh
- Starting setting: xhigh
- Start with Low; choose Medium or XHigh for more reasoning, or Off to disable thinking. High, Max and Ultra requests all map to XHigh.
- MiniMax M3
- Off / On
- Starting setting: On (High)
- High means On. Auto needs the native thinking.type=adaptive control; this setup's effort selector does not expose Auto. Check the current selection before sending.
| Model | What can I change? | Starting setting | What should I do? |
|---|---|---|---|
| DeepSeek Flash | Off / Low / High / Max | high | Start with Low; choose High or Max for more reasoning, or Off to disable thinking. Medium and XHigh requests map to High; Ultra maps to Max. |
| GLM-5.3-Flash | Low / High / Max | max | Choose Low for shorter reasoning, High for more reasoning, or Max for the largest budget. Thinking is always enabled; there is no Off option. The model default is Max unless the client sends a different effort. |
| MiMo V2.6 Flash | Off / On | On (High) | Choose On to enable thinking or Off to disable it. In clients that label On as High, choose High. There are no separate Low, Medium or High intensities. |
| MiMo V2.6 Pro | Off / On | On (High) | Choose On to enable thinking or Off to disable it. In clients that label On as High, choose High. There are no separate Low, Medium or High intensities. |
| GLM-5.3 | Low / High / Max | max | Choose Low for shorter reasoning, High for more reasoning, or Max for the largest budget. Thinking is always enabled; there is no Off option. The model default is Max unless the client sends a different effort. |
| Kimi-K3 | Low / High / Max | max | Choose Low for shorter reasoning, High for more reasoning, or Max for the largest budget. Thinking is always enabled; there is no Off option. The model default is Max unless the client sends a different effort. |
| Qwen3.8 Max | Off / Low / Medium / XHigh | xhigh | Start with Low; choose Medium or XHigh for more reasoning, or Off to disable thinking. High, Max and Ultra requests all map to XHigh. |
| MiniMax M3 | Off / On | On (High) | High means On. Auto needs the native thinking.type=adaptive control; this setup's effort selector does not expose Auto. Check the current selection before sending. |
Enter in the Agent ·Inside the Agent · send each command separately
/think
/think low
/status
/think high
/status
/think low
Restart the local OpenClaw Gateway after updating reasoning, thinkingLevelMap or compat. Higher levels need the supplied supportedReasoningEfforts declaration. Off must map to none; omitting effort does not guarantee thinking is disabled. Agent-specific defaults and session overrides can supersede shared model settings.
6. Choose a model and start working
Use /model in the TUI or the Control UI model picker. Select another multi-model-gateway entry; the provider key stays the same.
Open a project with a README.md and send the file-reading prompt below. Approve access to the file if prompted. You can switch models later without changing the key or gateway address.
Enter in the Agent ·Read a project file
Use the file-reading tool to read README.md in the selected project and summarize its purpose in one sentence. Do not modify any files.Switch models in OpenClaw
Use one command or picker entry at a time. An arrow means choose the entry in the picker; it is not part of a command. Your key must have access to the model you choose.
- DeepSeek Flash
/model multi-model-gateway/deepseek-flash - GLM-5.3-Flash
/model multi-model-gateway/glm-5.3-flash - MiMo V2.6 Flash
/model multi-model-gateway/mimo-flash - MiMo V2.6 Pro
/model multi-model-gateway/mimo-pro - GLM-5.3
/model multi-model-gateway/glm-5.3 - Kimi-K3
/model multi-model-gateway/kimi-k3 - Qwen3.8 Max
/model multi-model-gateway/qwen3.8-max - MiniMax M3
/model multi-model-gateway/minimax-m3
Connection reference
Keep these values consistent with the configuration above.
| Parameter | Value and purpose |
|---|---|
| Base URL | https://multi-api.deepseekv4pro.com/v1Keep the /v1 suffix in the provider base URL. |
| API protocol | OpenAI Chat Completions |
| API key | Use your delivered gateway key in the location shown in the setup steps. Replace credential placeholders locally. |
| Starting model | deepseek-flash |
Optional: check the API connection
Agent protocol: OpenAI Chat Completions. This Bash command uses the same API protocol with DeepSeek Flash. First export MULTI_MODEL_API_KEY in your terminal even if you saved the key in a settings file. The response should contain a short reply from DeepSeek Flash.
curl --fail-with-body "https://multi-api.deepseekv4pro.com/v1/chat/completions" \
  -H "Authorization: Bearer $MULTI_MODEL_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model":"deepseek-flash","messages":[{"role":"user","content":"Reply with a short hello."}],"max_tokens":256}'
Troubleshooting
- Models are missing
- Check the active config path, restart the Agent and look for project overrides. In Codex, check model_catalog_json; in OpenClaw, check model allowlists. Older Claude Code versions can use /model with an exact ID.
- 401 / 404
- 401: confirm the key is available to the running process. 404: check the model ID and base URL. Claude Code uses the root host; the other Agents here use /v1.
- 429 / unavailable endpoint
- Read the error for quota or provider capacity. Changing models does not refill points. Before activation, use only the confirmed endpoint supplied with your key.