Chinese Open-Source Model Developer Zhipu Releases Ultra-Fast New Model — GLM-5.3 Highspeed
TL;DRGLM-5.3 Highspeed has appeared in ZCode, with an early user reporting 490 output tokens per second. Pi lists the model as glm-5.3-highspeed. ZCode now documents a randomized GLM HighSpeed trial for subscribers; the reported speed and the proposed Omen Alpha connection remain unverified.
By DeepSeek V4 Hub
Zhipu has put a new model into circulation: GLM-5.3 Highspeed, turning up inside ZCode, the company's coding client. There's been no launch post, just users noticing a new name in the model list and starting to share screenshots.
The number getting passed around is 490 tokens per second, from a speed screenshot posted by an early user. That is within reach of 500 TPS.
TPS counts the tokens a model generates each second. Hold that pace and the generation stage of a 10,000-token output takes about 20 seconds.
This calculation covers output generation only: 10,000 ÷ 490 ≈ 20.4 seconds. It excludes reasoning time, time to first token, and tool calls. A single screenshot is not a controlled comparison across models.
For scale: GLM-5.3-FlashX, which Zhipu released only last month, tops out at 200 tokens/s. By Artificial Analysis' measurements, GLM-5.3-Flash on the Z.ai API produces roughly 60 tokens/s of output. So what exactly has Zhipu been feeding this one?
Easy next step: visit pricing to get your coding plan
The catalog listing was already out there
The GLM-5.3 Highspeed name had left traces before anyone spotted it in ZCode. Pi's model catalog carries a listing under the zai provider, and the specs read like the standard model: a 1,000,000-token context window, a 131,072-token output ceiling (about 128K), and three reasoning-effort settings — low, high, and max. Nothing about the configuration is new. The only thing that seems to have changed is the pace.
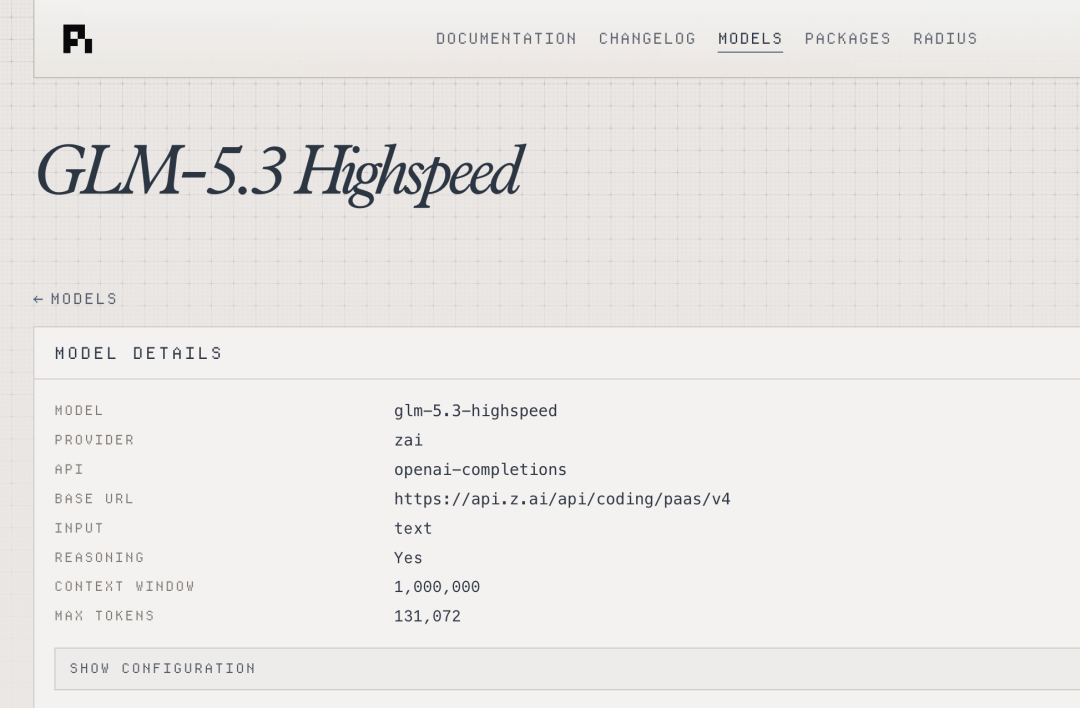
Pi's model catalog already lists glm-5.3-highspeed under the zai provider: 1M-token context window, 131,072-token output ceiling, reasoning supported.
The Omen Alpha question
Reddit users have been circling this model for weeks, and the leading theory ties it to Omen Alpha, an anonymous model that appeared in OpenCode's testing ground in September. In the same thread, Omen Alpha gets described as "almost identical to 5.3 flash but 3 times the amount of tk/s."
The community has more or less traced Omen Alpha back to Zhipu already: inside OpenCode, its identifier reads zhipu/omen-alpha.
Someone else ran the classic generation test, a pelican riding a bicycle, on the stealth model. The clip that came back stars a duck pedaling a bicycle.
The short version of the community's verdict: fast, willing to think for a long time, and the output quality holds up.
What Omen Alpha actually is remains unsettled. Some say it is GLM-5.3 Highspeed itself; others are guessing GLM-5.3-Omni or GLM-5.4-Flash.
Zhipu has run this play before
This is not Zhipu's first highspeed model. In May the company shipped GLM-5.1 Highspeed, which generated at 400 tokens/s and essentially reset the output-speed ceiling among major model providers' APIs at the time. If GLM-5.3 Highspeed genuinely sustains 490 TPS, long agent runs get meaningfully shorter to sit through.
For now the new model is in randomized gray-release inside ZCode. An Ask ZCode answer citing the changelog describes GLM HighSpeed as a subscription-side perk handed out at random: after the update, the system picks a subset of subscribers and grants them the accelerated experience. Picked users get the speed; everyone else is unaffected. Whether you're in, and where the entry point appears, is shown by prompts inside the client.
October 13 update: ZCode’s official release notes for version 3.15.1, dated October 12, list a randomized GLM HighSpeed trial for subscribers. This supports the limited-access account above, but does not independently establish the 490 TPS figure or identify the model behind Omen Alpha.
What should you check before trying Highspeed?
- Check whether your ZCode account actually shows the trial; a subscription alone does not guarantee selection.
- Record the client version and selected model name before comparing output speed.
- Compare completion time and output quality on the same task, rather than treating TPS as a complete measure of agent performance.
Sources
- Speed screenshot shared on X
- Pi model catalog: zai/glm-5.3-highspeed
- r/ZaiGLM: GLM-5.3 Highspeed??
- ZCode official release notes — v3.15.1, October 12, 2026: randomized subscriber access to the GLM HighSpeed trial.